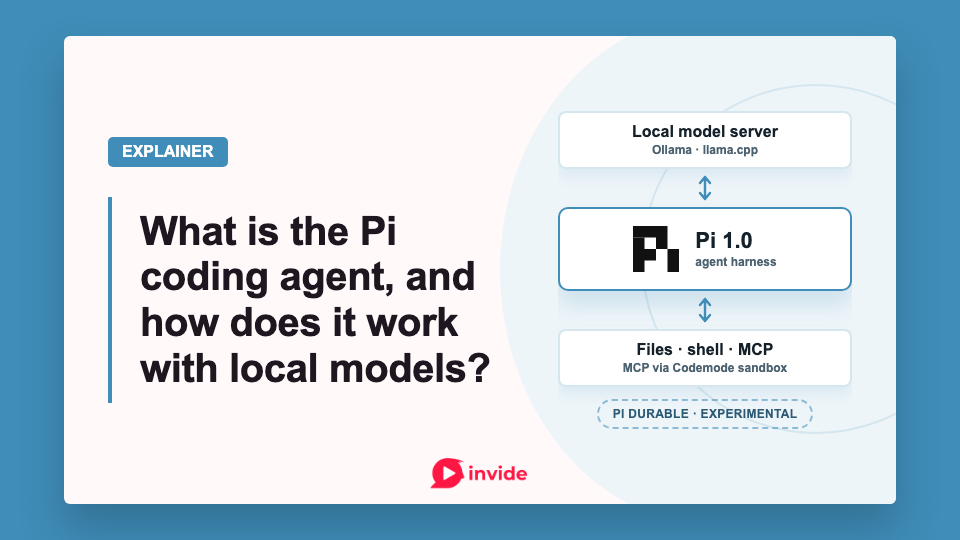
What is the Pi coding agent, and how does it work with local models?
Pi 1.0 shipped on October 1 with built-in MCP support through Codemode, after Earendil publicly rejected MCP. Here's how to run it against Ollama or llama.cpp, which packages you need, and when the experimental Pi Durable framework fits.
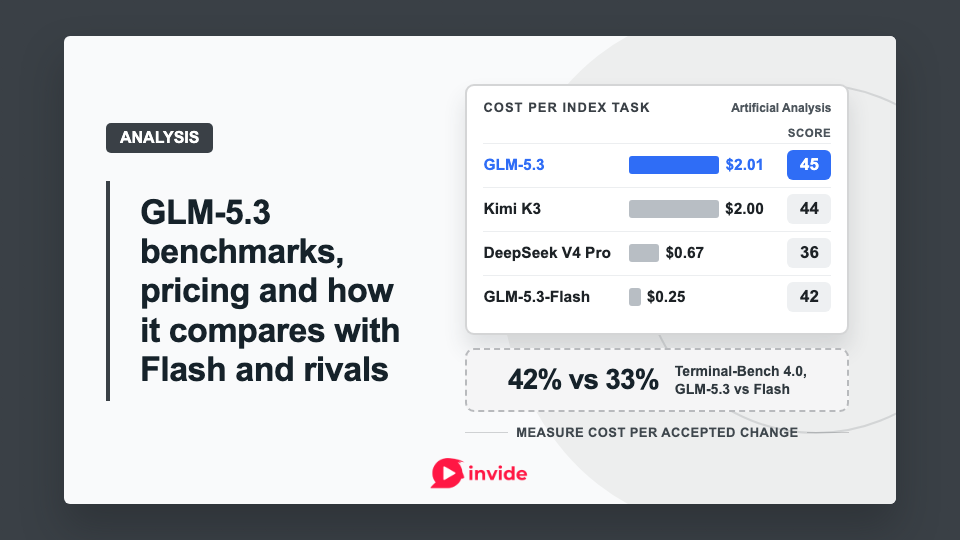
GLM-5.3 benchmarks, pricing and how it compares with Flash and rivals
GLM-5.3 keeps GLM-5.2's list price and matches Kimi K3's cost per Artificial Analysis index task. DeepSeek V4 Pro costs a third as much on the same index. Existing users must update requests that disable thinking.
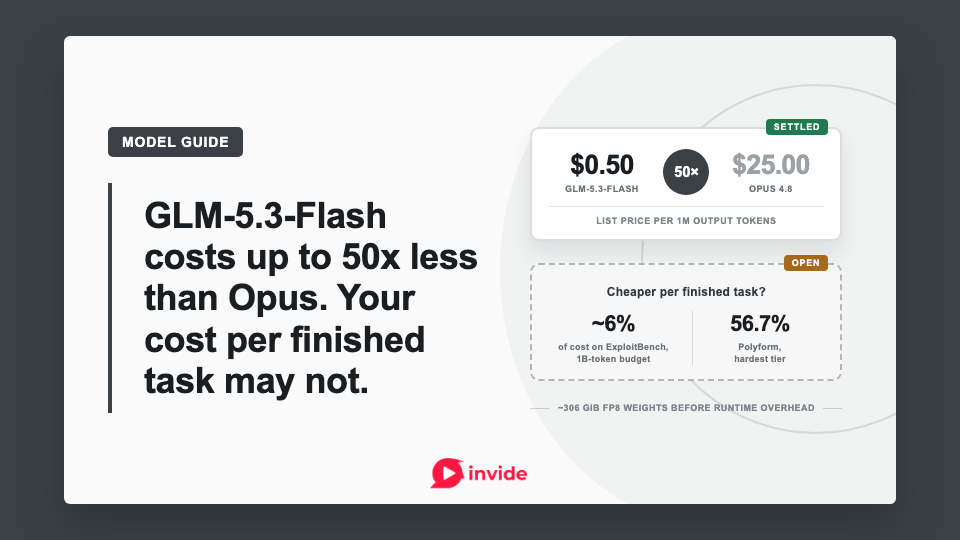
GLM-5.3-Flash costs up to 50x less than Opus. Your cost per finished task may not.
Given a billion tokens per vulnerability, GLM-5.3-Flash matched Claude Mythos Preview on ExploitBench at roughly 6% of the cost, while one production team found it fine for bounded work and not ready for their hardest tier.
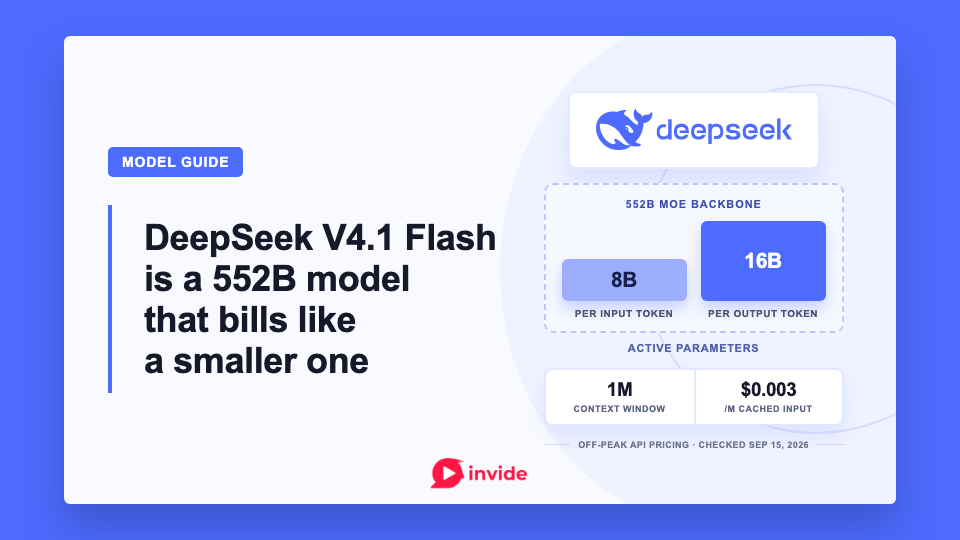
DeepSeek V4.1 Flash is a 552B model that bills like a smaller one
DeepSeek V4.1 Flash activates 8B parameters per input token and prices cached input from $0.003 per million. On Terminal-Bench 4.0, it scores 31.2 to Opus 5.0's 51.8.
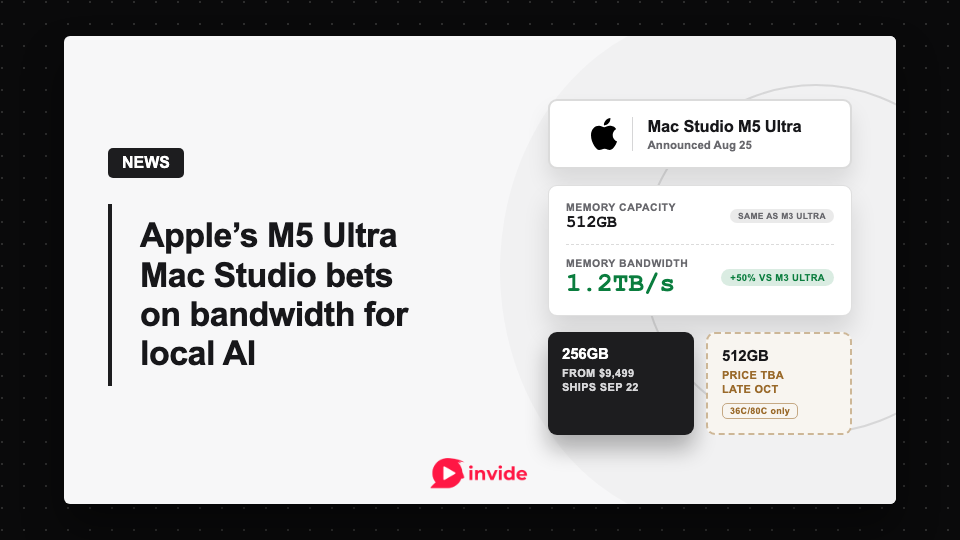
Apple's M5 Ultra Mac Studio bets on bandwidth for local AI
Apple kept M5 Ultra's 512GB ceiling but raised bandwidth to 1.2TB/s. The 256GB model starts at $9,499; prompt-prefill gains remain untested.
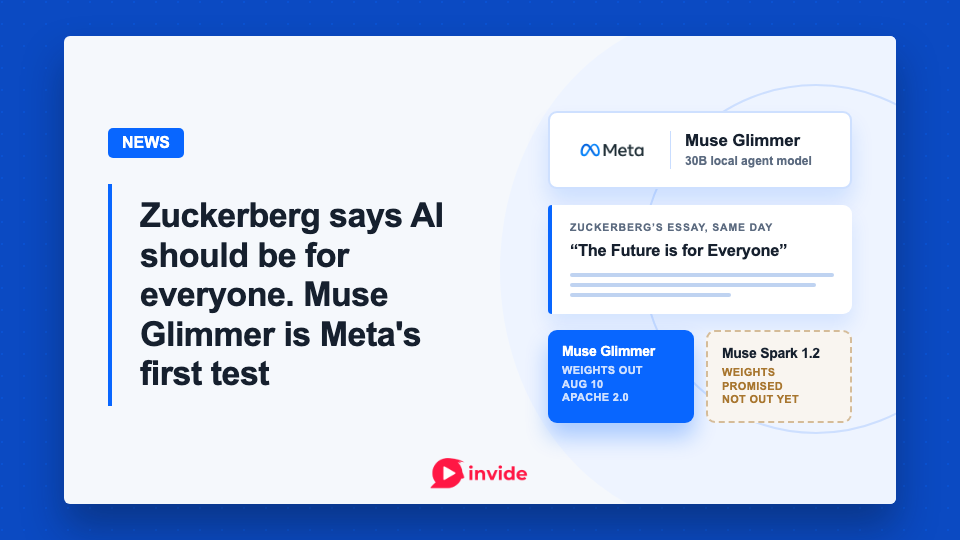
Zuckerberg says AI should be for everyone. Muse Glimmer is Meta’s first test
Muse Glimmer is a real 30B Apache 2.0 release, but its performance on common hardware, independent benchmark results, and Meta’s promised follow-ups remain open.
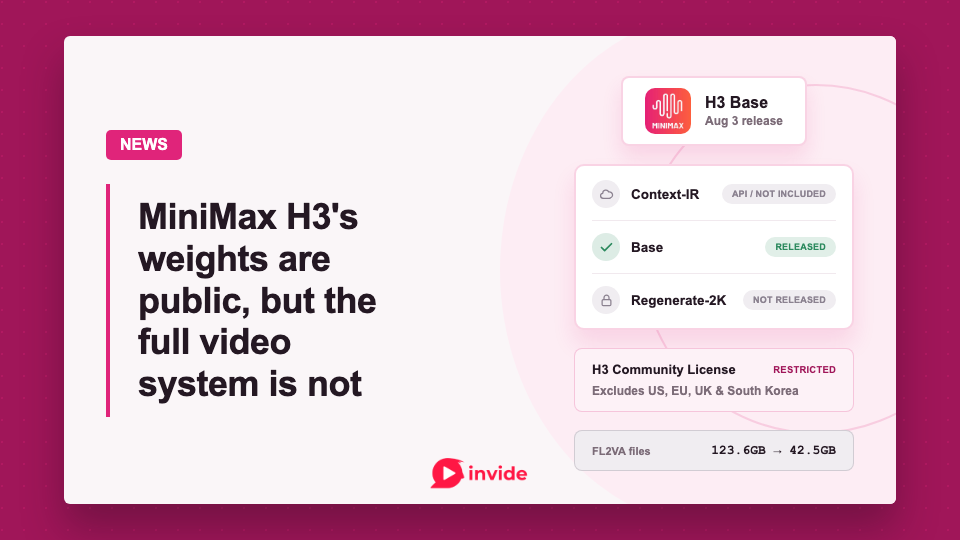
MiniMax H3’s weights are public, but the full video system is not
MiniMax released H3 Base weights with local ComfyUI workflows, but its restricted license, large downloads, and missing 2K modules limit practical use.
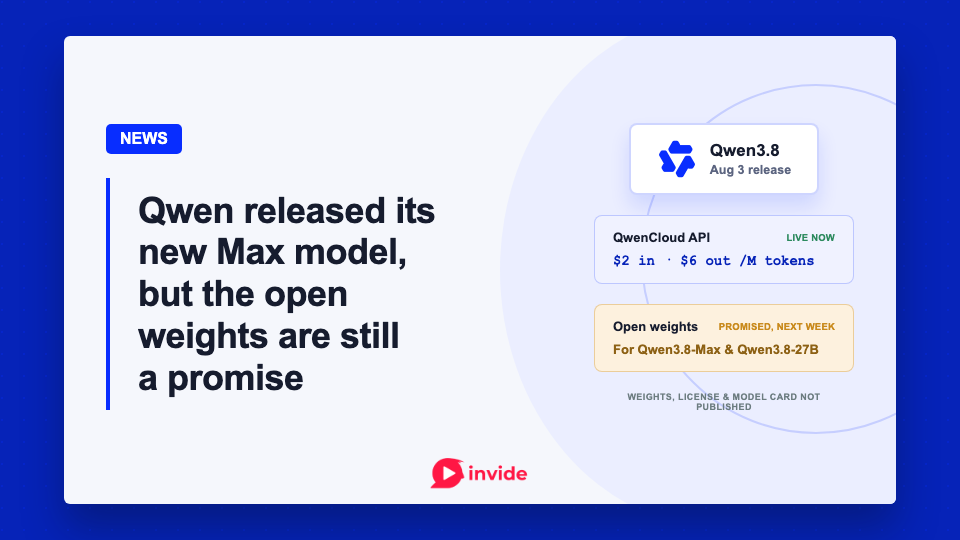
Qwen released its new Max model, but the open weights are still a promise
Qwen released Qwen3.8-Max and promised open weights for it and a new 27B model next week, but developers still need the artifacts, license, and local tests.
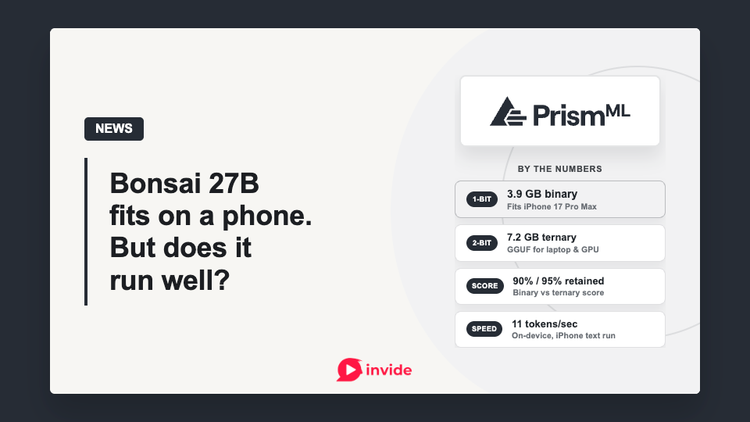
Bonsai 27B fits on a phone. But does it run well?
PrismML compressed a 27B-class model into a phone-sized package, but kernels, memory overhead, and real device performance still determine whether it is practical.